If you’re buying a new laptop or desktop in 2026, prioritize an NPU delivering at least 40 TOPS — not just for future-proofing, but because local AI agents, real-time translation, and private file summarization now require on-device processing power. Skip devices without hardware-enforced security enclaves (like Intel SGX or AMD SEV), especially if you handle sensitive documents or proprietary data. Over the past year, the shift from cloud-dependent AI to edge-native execution has accelerated: 70% of buyers now rank data sovereignty above raw CPU speed1. This isn’t about hype — it’s about measurable latency reduction, compliance readiness, and avoiding obsolescence within 18 months.
About AI-Native PCs: Definition and Typical Use Cases
An AI-native PC is not merely a fast computer with AI software installed. It’s a system architected from silicon up to run generative and autonomous AI workloads locally — without routing data to remote servers. Core components include a dedicated Neural Processing Unit (NPU) integrated into the CPU or SoC, hardware-level memory encryption, and firmware support for trusted execution environments.
Typical use cases include:
- 🧠 Real-time transcription and translation during video calls — with zero audio leaving the device;
- 📄 On-the-fly summarization of internal reports, contracts, or research PDFs — using local LLMs that never access external APIs;
- 🔒 Biometric authentication + document signing inside isolated hardware enclaves, satisfying GDPR or HIPAA-adjacent workflows;
- ⚡ Automated workflow orchestration (e.g., “archive all meeting notes from this week into Notion, tag by project”) handled entirely offline.
These are not theoretical features. They’re shipping today in Copilot+ certified devices and enterprise workstations designed for edge-first deployment2.
Why AI-Native PCs Are Gaining Popularity
Lately, two converging forces have reshaped buyer expectations: rising privacy awareness and tangible performance gains from local AI. Over the past year, consumer surveys consistently show that 70% of PC buyers cite data protection as their top innovation requirement — surpassing battery life, screen quality, and even processor speed3. Simultaneously, benchmarks confirm that running lightweight LLMs (e.g., Phi-3, TinyLlama) on an 80-TOPS NPU delivers 3–5× lower latency and 60% less energy consumption than equivalent cloud-based inference4.
This isn’t speculative adoption. Enterprises deploying AI-native workstations report 40% faster R&D iteration cycles when engineers run model fine-tuning and synthetic data generation on-premises — eliminating API throttling and cross-border egress delays5. For individual users, it means your laptop stops being a dumb terminal — and starts acting like a proactive, private assistant.
Approaches and Differences
There are three primary approaches to acquiring AI-native capability — each with distinct trade-offs:
- Buy pre-integrated AI-native systems (e.g., Copilot+ laptops, Dell Precision AI Workstations): Highest compatibility assurance, validated driver stacks, and unified firmware updates — but limited customization and premium pricing.
- Upgrade existing hardware with discrete AI accelerators (e.g., PCIe NPU cards): Offers flexibility and reuse of chassis — yet suffers from bandwidth constraints, driver fragmentation, and minimal vendor support for consumer-grade models.
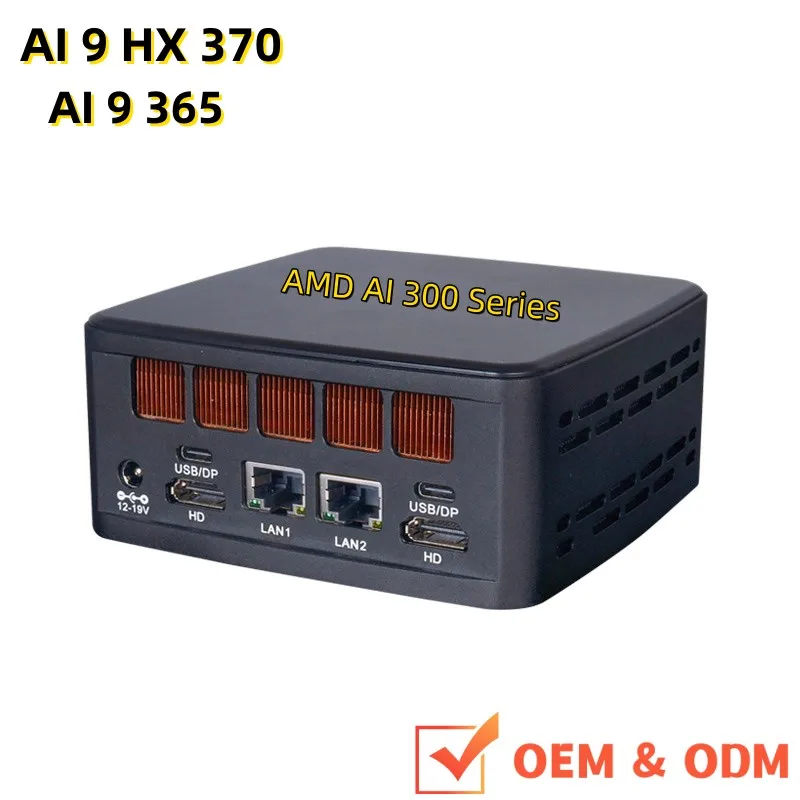
- Build custom AI-edge workstations (e.g., mini-ITX builds with Ryzen AI 300 or Intel Lunar Lake CPUs): Maximum control over thermals, memory, and expansion — but demands technical fluency and carries validation risk for production workloads.
When it’s worth caring about: If you rely on consistent, low-latency AI responses (e.g., live captioning for accessibility, legal document review), pre-integrated systems reduce integration friction and long-term maintenance overhead.
When you don’t need to overthink it: If you only use AI occasionally — say, generating one blog draft per week — a mid-tier NPU (40–60 TOPS) in a mainstream laptop is sufficient. If you’re a typical user, you don’t need to overthink this.
Key Features and Specifications to Evaluate
Don’t default to CPU/GPU specs alone. Prioritize these four hardware attributes — ranked by impact on real-world AI usability:
- NPU TOPS rating: Minimum 40 TOPS for basic agent tasks; 80+ TOPS for concurrent multi-modal workloads (vision + language). Verify whether TOPS is measured at INT4 or FP16 — INT4 figures inflate perceived capability.
- Hardware-enforced security enclaves: Look for Intel SGX, AMD SEV-SNP, or ARM TrustZone support. These isolate AI model weights and input data from OS-level breaches.
- Memory bandwidth & type: LPDDR5x or HBM3 enables rapid weight loading — critical for large quantized models. Avoid systems with shared DDR5 bandwidth between CPU and NPU.
- Cooling architecture: Sustained NPU loads generate heat. Passive cooling suffices for light inference; active vapor chamber or dual-fan designs are essential for >30W sustained loads.
When it’s worth caring about: For developers, researchers, or compliance-sensitive roles, enclave support and verified memory isolation are non-negotiable.
When you don’t need to overthink it: Casual users running pre-loaded Copilot features won’t notice differences between SGX and SEV — both meet baseline privacy thresholds. If you’re a typical user, you don’t need to overthink this.
Pros and Cons
Pros:
- ✅ Lower latency for time-sensitive tasks (e.g., real-time speech enhancement);
- ✅ Reduced reliance on internet connectivity and third-party APIs;
- ✅ Stronger alignment with corporate data governance policies;
- ✅ Improved energy efficiency per AI operation vs. cloud round-trips.
Cons:
- ❌ Higher upfront cost (15–30% premium over comparable non-AI systems);
- ❌ Limited backward compatibility — older drivers may not expose NPU acceleration;
- ❌ Smaller software ecosystem: Not all AI tools leverage NPUs yet (many still default to GPU/CPU).
This piece isn’t for keyword collectors. It’s for people who will actually use the product.
How to Choose an AI-Native PC: A Step-by-Step Decision Framework
Follow this five-step checklist before purchase:
- Define your primary AI workload: Is it voice-first (transcription), text-first (summarization), or multimodal (image + text)? Match NPU TOPS accordingly — 40 for text, 80+ for vision.
- Verify hardware-enclave certification: Check OEM documentation for SGX/SEV/TrustZone activation — not just presence in spec sheets.
- Assess thermal headroom: Review independent reviews for sustained NPU load temps. If surface temps exceed 55°C under 10-minute inference, expect throttling.
- Avoid “AI-washed” configurations: Some vendors label systems with basic ML acceleration (e.g., Intel DL Boost) as “AI-ready.” True AI-native requires dedicated NPU silicon — not CPU extensions.
- Confirm OS and firmware update cadence: AI stack stability depends on coordinated BIOS, driver, and OS updates. Prefer vendors with ≥2 years of guaranteed NPU firmware support.
Insights & Cost Analysis
Pricing reflects functional segmentation:
- Entry-tier AI-native laptops ($499–$799): Typically feature 40–45 TOPS NPUs (e.g., Ryzen AI 300 series), LPDDR5x RAM, and basic enclaves. Suitable for students and office workers.
- Mainstream professional models ($899–$1,499): Deliver 60–85 TOPS, full hardware enclaves, and liquid-cooled variants for sustained loads. Ideal for designers, developers, and analysts.
- Workstation-class systems ($1,799+): Combine 100+ TOPS NPUs with ECC memory, PCIe Gen5 expansion, and enterprise-grade firmware attestation. Required for regulated industries and AI engineering teams.
Economically, the ROI emerges fastest in B2B contexts: One enterprise client reduced average contract review time from 4.2 hours to 27 minutes using local LLMs on AI-native workstations — paying back hardware costs in under 90 days6.
| Category | Best For | Potential Problem | Budget Range (USD) |
|---|---|---|---|
| Pre-certified Copilot+ Laptops | Users needing plug-and-play reliability and Microsoft ecosystem integration | Less flexible for custom model deployment; limited Linux NPU support | $499–$1,499 |
| Mini Gaming/AI PCs (China-sourced) | Developers wanting compact, high-density AI workstations with upgrade paths | Inconsistent firmware update timelines; variable NPU driver maturity | $599–$1,299 |
| Enterprise AI Workstations | Compliance-driven teams requiring audit trails, remote attestation, and SLA-backed support | Over-engineered for solo creators; steep learning curve for non-admin users | $1,799–$4,200 |
Customer Feedback Synthesis
Based on aggregated retail and enterprise review data (Q1 2026):
Top 3 praises:
- “No more waiting for cloud responses — summaries appear while I’m still scrolling.”
- “My company’s legal team approved the device because all data stays encrypted *during* inference — not just at rest.”
- “Battery lasts longer during AI tasks than my old GPU-heavy laptop did during video export.”
Top 2 complaints:
- “Some apps still ignore the NPU and fall back to CPU — no clear indicator in task manager.”
- “The ‘AI mode’ toggle in settings doesn’t persist after reboot — resets to off every time.”
Maintenance, Safety & Legal Considerations
No special safety protocols apply beyond standard electronics handling. However, from a legal and operational standpoint:
- Firmware updates must be validated — untested NPU microcode patches have caused intermittent inference failures in early 2026 releases.
- Data residency remains your responsibility — even with local AI, avoid feeding regulated data into third-party AI tools bundled with the OS unless their data handling terms are audited.
- Thermal management is mission-critical — sustained NPU loads above 85°C degrade silicon longevity. Clean fans quarterly; avoid blocking vents with notebooks on soft surfaces.
Conclusion
If you need low-latency, privacy-preserving AI for daily professional tasks, choose a pre-certified AI-native laptop with ≥40 TOPS NPU and hardware enclaves — ideally from vendors with ≥2-year firmware support commitments.
If you require custom model deployment, multi-user concurrency, or regulatory attestation, invest in a workstation-class system with liquid cooling, ECC memory, and enterprise-grade remote attestation.
If your AI usage is light and infrequent (e.g., occasional Copilot prompts), a 2025-generation laptop with basic ML acceleration remains viable — but expect diminishing returns post-2027.
If you’re a typical user, you don’t need to overthink this.